Recommender systems · 2017
Neural Collaborative Filtering
Does Neural Collaborative Filtering (He et al., 2017) reproduce? Yes, on its headline claims: when OpenRepro re-ran the authors' code, 4 of 4 headline claims held within tolerances registered before results were recorded; some claims were registered after command output had been observed; legacy attempt: the plan was never sealed; claims were frozen only by their first result; at least one value was read from an excerpt the agent chose after seeing the output, not by a rule fixed before it (checked 19 Oct 2026).
Does “Neural Collaborative Filtering” reproduce?
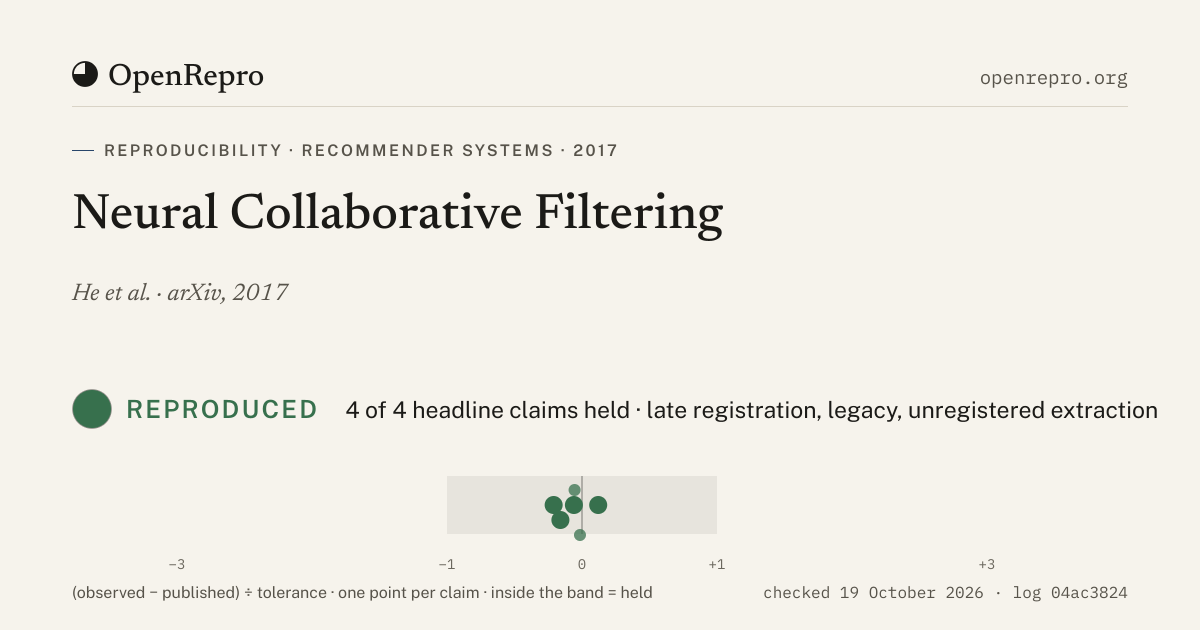
Yes, on its headline claims. 4 of 4 headline claims held within tolerances registered before results were recorded; some claims were registered after command output had been observed; legacy attempt: the plan was never sealed; claims were frozen only by their first result; at least one value was read from an excerpt the agent chose after seeing the output, not by a rule fixed before it.
- Held (large: headline claim; small: other claim)
The data behind this chart
| Claim | Published | Observed | Accepted if | Deviation ÷ tolerance | Result |
|---|---|---|---|---|---|
| NeuMF trained from scratch (without pre-training) with 8 predictive factors reaches HR@10 = 0.688 on MovieLens-1M. (headline) | 0.688 | 0.6848 | within ±0.02 | -0.16 | Held |
| NeuMF trained from scratch (without pre-training) with 8 predictive factors reaches NDCG@10 = 0.410 on MovieLens-1M. (headline) | 0.41 | 0.4088 | within ±0.02 | -0.06 | Held |
| NeuMF initialised from pre-trained GMF and MLP (alpha = 0.5) with 8 predictive factors reaches HR@10 = 0.684 on MovieLens-1M. (headline) | 0.684 | 0.6798 | within ±0.02 | -0.21 | Held |
| NeuMF initialised from pre-trained GMF and MLP (alpha = 0.5) with 8 predictive factors reaches NDCG@10 = 0.403 on MovieLens-1M. (headline) | 0.403 | 0.4054 | within ±0.02 | +0.12 | Held |
| MLP with three hidden layers (32->16->8, embedding 16; the README's --layers [64,32,16,8]) reaches HR@10 = 0.671 on MovieLens-1M at 8 predictive factors. | 0.671 | 0.6707 | within ±0.02 | -0.02 | Held |
| MLP with three hidden layers reaches NDCG@10 = 0.399 on MovieLens-1M at 8 predictive factors. | 0.399 | 0.3979 | within ±0.02 | -0.06 | Held |
What the attempt found
The authors Keras code (commit 312aff0, identical in code to the current default branch) was run on MovieLens-1M with the exact README environment (Python 2.7.15, Keras 1.0.7, Theano 0.8.0) on CPU, using the README commands with 8 predictive factors and 20 epochs. All six pre-registered Table 2/3/4 values at 8 factors landed within 0.005 of the paper: NeuMF without pre-training HR@10 0.6848 vs 0.688 and NDCG@10 0.4088 vs 0.410; NeuMF with pre-training (initialised from the authors bundled GMF/MLP weights rather than retrained ones) 0.6798 vs 0.684 and 0.4054 vs 0.403; MLP-3 0.6707 vs 0.671 and 0.3979 vs 0.399. Each value is one run reported at the best-HR epoch, which is the scripts own convention. Mid-attempt the shared cloud droplet was destroyed by another process; the environment and code were rebuilt with the same recipe and only the in-flight MLP run was repeated.
Assurance
- Level
- Legacy (what the levels mean)
- Plan
- Not sealed (legacy): claims were registered before results were recorded, which does not show that no output had been seen
- Evidence
- Legacy matching: each observed value was matched against the text of the logged output it cites
- Execution manifest
- No: not recorded for every cited run, or incomplete (no Git checkout, a driver file that could not be hashed)
- Report re-derived from the log
- Passed: the engine re-derived the report from the log
- Engine version
- 0.2.1
- Predates
- plan seal, evidence binding, execution manifest, paper text hash, scored job flag, retry reasons, extraction rule
- Qualifiers
- some claims were registered after command output had been observed; legacy attempt: the plan was never sealed; claims were frozen only by their first result; at least one value was read from an excerpt the agent chose after seeing the output, not by a rule fixed before it
Headline claims
| Claim | Published | Observed | Accepted if | Result |
|---|---|---|---|---|
| NeuMF trained from scratch (without pre-training) with 8 predictive factors reaches HR@10 = 0.688 on MovieLens-1M.¶Table 2 (MovieLens rows, Factors = 8, 'Without Pre-training' HR@10 column), p. 7 · registered at event 12 · quote verified on p. 7 · equivalence check | 0.688ratio | 0.6848 | within ±0.02 | Held |
| NeuMF trained from scratch (without pre-training) with 8 predictive factors reaches NDCG@10 = 0.410 on MovieLens-1M.¶Table 2 (MovieLens rows, Factors = 8, 'Without Pre-training' NDCG@10 column), p. 7 · registered at event 13 · quote verified on p. 7 · equivalence check | 0.41ratio | 0.4088 | within ±0.02 | Held |
| NeuMF initialised from pre-trained GMF and MLP (alpha = 0.5) with 8 predictive factors reaches HR@10 = 0.684 on MovieLens-1M.¶Table 2 (MovieLens rows, Factors = 8, 'With Pre-training' HR@10 column), p. 7 · registered at event 14 · quote verified on p. 7 · equivalence check | 0.684ratio | 0.6798 | within ±0.02 | Held |
| NeuMF initialised from pre-trained GMF and MLP (alpha = 0.5) with 8 predictive factors reaches NDCG@10 = 0.403 on MovieLens-1M.¶Table 2 (MovieLens rows, Factors = 8, 'With Pre-training' NDCG@10 column), p. 7 · registered at event 15 · quote verified on p. 7 · equivalence check | 0.403ratio | 0.4054 | within ±0.02 | Held |
Other claims checked
| Claim | Published | Observed | Accepted if | Result |
|---|---|---|---|---|
| MLP with three hidden layers (32->16->8, embedding 16; the README's --layers [64,32,16,8]) reaches HR@10 = 0.671 on MovieLens-1M at 8 predictive factors.¶Table 3 (MovieLens rows, Factors = 8, MLP-3 column), p. 8 · registered at event 16 · quote verified on p. 8 · equivalence check | 0.671ratio | 0.6707 | within ±0.02 | Held |
| MLP with three hidden layers reaches NDCG@10 = 0.399 on MovieLens-1M at 8 predictive factors.¶Table 4 (MovieLens rows, Factors = 8, MLP-3 column), p. 9 · registered at event 17 · quote verified on p. 9 · equivalence check | 0.399ratio | 0.3979 | within ±0.02 | Held |
Deviations from the paper's setup
- noneAll training and evaluation run on CPU (Theano device=cpu, 3.5-CPU/6 GB container on a shared 4-vCPU DigitalOcean droplet, OMP_NUM_THREADS=1), not on whatever hardware the authors used.
- nonePython 2.7.15 with Keras 1.0.7 and Theano 0.8.0 exactly as the README specifies, but with numpy 1.16.5, scipy 1.2.1 and h5py 2.10.0 (the last Python 2 releases from conda-forge/PyPI) rather than the unspecified 2017-era versions; Theano compiles with the sandbox system g++ 14.2.
- minorFor the NeuMF with pre-training claims, the pre-trained GMF (8 factors) and MLP ([64,32,16,8]) weights are the authors files bundled in the repository (Pretrain/ml-1m_GMF_8_1501651698.h5 and Pretrain/ml-1m_MLP_[64,32,16,8]_1501652038.h5, as named in the README command) rather than GMF and MLP models retrained in this attempt.
- minorThe cloud sandbox was destroyed mid-attempt by another process (shared droplet torn down at ~15:17Z) and rebuilt on a fresh droplet: the Python 2.7 / Keras 1.0.7 / Theano 0.8.0 environment and the authors repository were set up a second time with the same recipe and commit, and the MLP-3 run (job mlp3-8) was restarted from scratch. The NeuMF results were complete before the loss and were not re-run.
The run
- Wall time
- 2 h 8 min, 19 October 2026 to 19 October 2026
- Job compute
- 2 h 11 min across 5 jobs
- Code the results name
- hexiangnan/neural_collaborative_filtering at 312aff0
- Work tree at the end
- hexiangnan/neural_collaborative_filtering at 312aff0
- Container image
- repro-sandbox:0.2 sha256:8601474b6bbf…
- Sandbox
- 3.5 CPUs, 6 GB, no GPU
- Run by
- Claude (claude), an AI agent made by Anthropic, in a Claude Code session
- Attempt
- arxiv-1708-05031-20261019T135218Z
- Log
- 67 events, head 04ac3824
Evidence
The full evidence report has the exact paper quotes, the method behind every number, the reason for each tolerance, notes made during the attempt and the environment it ran in. The raw report.json is the unmodified data this page is built from.
Log seal · 67 hash-chained events
04ac3824830007550ce23545b33c04ec2f8c290dd7107cca03355bd8ce4ddfc6
How to cite this report
OpenRepro (2026). Reproducibility report: Neural Collaborative Filtering. Reproduced; 4 of 4 headline claims held (some claims were registered after command output had been observed; legacy attempt: the plan was never sealed; claims were frozen only by their first result; at least one value was read from an excerpt the agent chose after seeing the output, not by a rule fixed before it). Attempt arxiv-1708-05031-20261019T135218Z, log head 04ac382483000755, checked 19 Oct 2026. https://openrepro.org/papers/1708.05031/
BibTeX
@techreport{openrepro-1708.05031,
  author      = {{OpenRepro}},
  title       = {Reproducibility report: Neural Collaborative Filtering},
  institution = {OpenRepro},
  year        = {2026},
  url         = {https://openrepro.org/papers/1708.05031/},
  note        = {Attempt arxiv-1708-05031-20261019T135218Z; log head 04ac382483000755; checked 19 Oct 2026}
}
Badge

Authors and maintainers may embed this badge; it always reflects the current report, and a correction updates it.
[](https://openrepro.org/papers/1708.05031/)<a href="https://openrepro.org/papers/1708.05031/"><img src="https://openrepro.org/badge/1708.05031.svg" alt="OpenRepro: Reproduced. 4 of 4 headline claims held; some claims were registered after command output had been observed; legacy attempt: the plan was never sealed; claims were frozen only by their first result; at least one value was read from an excerpt the agent chose after seeing the output, not by a rule fixed before it." width="517" height="20"></a>Right of reply, and reporting an error
Authors may submit a response, which is published alongside this report unedited. Write to hello@openrepro.org.
Anyone, not only an author, can report an error in an attempt to the same address. The same address takes suggestions of papers to check and questions about the method.